Agentic forecasting step-by-step
skforecast-ai is an AI forecasting assistant that pairs a deterministic engine, powered by skforecast, with an LLM reasoning layer. Simply provide a time series, and the assistant automatically profiles the data, selects a model using established best practices, and evaluates its performance. It returns both the final forecast and the runnable skforecast script that produced it.
This tutorial walks through the step-by-step path: the approach for users who want granular control to inspect or adjust intermediate decisions before committing to a full run. If you prefer a single-call workflow that returns results immediately, see the fast-path tutorial.
Both paths share the same deterministic engine and produce identical results and reproducible skforecast code. The step-by-step path gives you three additional capabilities:
Inspect intermediate objects: examine the
ForecastingProfileandForecastPlanbefore any model is trained, and confirm the assistant's recommendations make sense for your domain.Override any single decision: change the forecaster, the estimator and its hyperparameters, the lags, the window features, the horizon or the interval without re-running the entire pipeline from scratch. Pass the modified plan directly to
forecast()orbacktest().Reuse the profile and plan across branches: build the profile and plan once, then run
forecast()for future predictions,backtest()for historical evaluation, andcompare()to rank several candidate configurations: each reusing the same profile, with no redundant profiling.
The ask() method is available at every stage. It interprets what you pass to it (a profile, a plan, a generated script, a cross-validation strategy, a forecast result, a backtest result, or a comparison result), but it never executes the workflow or silently changes any recommendation.
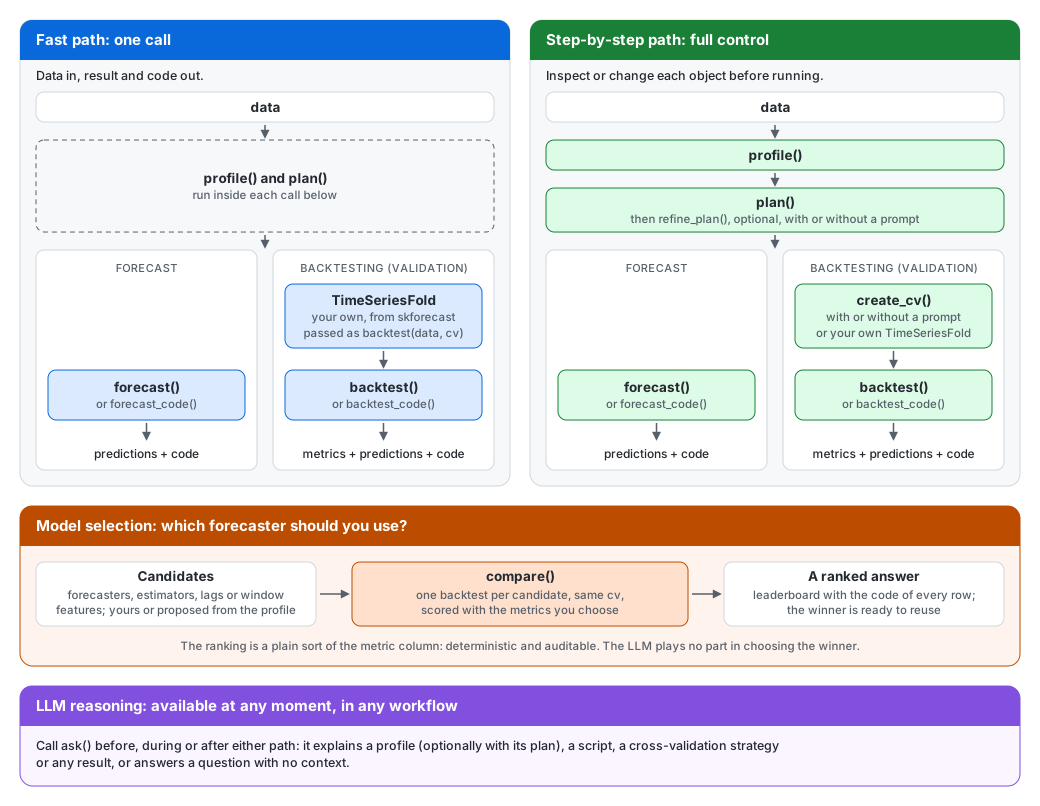
The following example walks through the step-by-step path, allowing users to understand and control what happens under the hood. If you prefer the quickest way to go from raw data to a validated forecast with minimal setup, visit the fast-path tutorial.
Assistant initialization
The first step is to instantiate a ForecastingAssistant, which will be responsible for executing the entire workflow (profiling, planning, backtesting, and forecasting), as well as explaining the outputs and suggesting improvements.
To activate the optional LLM support, users must pass a string in the format 'provider:model_name' (for example, 'openai:gpt-5.5', 'google:gemini-3.8-flash', 'anthropic:claude-sonnet-5', or 'ollama:qwen3:8b'). For hosted providers, the corresponding API key must be available as an environment variable or passed explicitly when creating the assistant. Your dataset is never sent: the LLM receives only metadata and summary statistics, never the raw time series values. In this tutorial, we keep send_data_to_llm=False (the default), so passing a result to ask(), whose own predictions and metrics are sent, emits a DataSentToLLMWarning as a reminder.
# Data processing
# ==============================================================================
import os
import pandas as pd
from skforecast.datasets import fetch_dataset

# Plots
# ==============================================================================
import matplotlib.pyplot as plt
import plotly.graph_objects as go
import plotly.io as pio
import plotly.offline as poff
pio.templates.default = "seaborn"
poff.init_notebook_mode(connected=True)
plt.style.use('seaborn-v0_8-darkgrid')

# skforecast and skforecast-ai
# ==============================================================================
import skforecast
import skforecast_ai
from skforecast_ai import ForecastingAssistant
from skforecast.model_selection import TimeSeriesFold
from skforecast.plot import set_dark_theme

# Python utilities
# ==============================================================================
import textwrap

color = '\033[1m\033[38;5;208m'
print(f"{color}Version skforecast_ai: {skforecast_ai.__version__}")
print(f"{color}Version skforecast: {skforecast.__version__}")
Version skforecast_ai: 0.4.2
Version skforecast: 0.26.0
✏️ Note
If you do not have access to an LLM, you can still follow the full tutorial using only the deterministic methods. Profiling, planning, backtesting, and forecasting all run without an LLM. Only the ask() explanations and the LLM-guided variants of refine_plan() and create_cv() require a configured LLM; their deterministic counterparts work without one.
# LLM-enabled assistant
# ==============================================================================
LLM_MODEL = "google:gemini-3.8-flash"
api_key = os.getenv("GOOGLE_API_KEY")

assistant = ForecastingAssistant(
    llm=LLM_MODEL, api_key=api_key, send_data_to_llm=False
)

# Using AWS Bedrock
# ==============================================================================
# assistant = ForecastingAssistant(
#     llm='bedrock:eu.anthropic.claude-sonnet-4-6',
#     base_url="eu-west-1"
# )

# Assistant without LLM (deterministic only)
# ==============================================================================
# assistant = ForecastingAssistant()
Before going on, check_llm() reports how the configuration resolves (provider, credentials, endpoint, installed extras) without calling the model, so a missing key shows up here instead of in the first ask(). See Configuring the LLM for the details.
# Check the LLM configuration
# ==============================================================================
assistant.check_llm()
                          LLM Configuration Check
┏━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Check        ┃ Value                                                     ┃
┡━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ Status       │ ok                                                        │
├──────────────┼───────────────────────────────────────────────────────────┤
│ Provider     │ google                                                    │
├──────────────┼───────────────────────────────────────────────────────────┤
│ Model        │ gemini-3.8-flash                                          │
├──────────────┼───────────────────────────────────────────────────────────┤
│ Credentials  │ explicit api_key                                          │
│              │ Explicit api_key given; the environment is not consulted. │
├──────────────┼───────────────────────────────────────────────────────────┤
│ Base URL     │ None                                                      │
├──────────────┼───────────────────────────────────────────────────────────┤
│ Dependencies │ installed                                                 │
├──────────────┼───────────────────────────────────────────────────────────┤
│ Test call    │ skipped                                                   │
└──────────────┴───────────────────────────────────────────────────────────┘
⚠️ Your data stays private
Enabling an LLM never sends your time-series data to the model provider.
The assistant passes only a summary of the dataset (frequency, date range, target statistics,
missing values, significant lags) and the forecaster configuration, never the raw observations.
Results passed to ask() are the exception: their own predictions and metrics are
sent, because a question about a result cannot be answered from summary statistics alone, and a
DataSentToLLMWarning reminds you of it. Pass send_data_to_llm=True to
acknowledge it and silence the warning. See
What is sent to the LLM for the full list.
Data
The data used in this tutorial represent the hourly usage of the bike share system in the city of Washington, D.C. during the years 2011 and 2012. In addition to the number of users per hour, information about weather conditions and holidays is available.
# Downloading data
# ==============================================================================
data = fetch_dataset('bike_sharing', raw=True)
data = data[['date_time', 'users', 'holiday', 'weather', 'temp']]
data['date_time'] = pd.to_datetime(data['date_time'])
data.head()
╭───────────────────────────────── bike_sharing ──────────────────────────────────╮
│ Description:                                                                    │
│ Hourly usage of the bike share system in the city of Washington D.C. during the │
│ years 2011 and 2012. In addition to the number of users per hour, information   │
│ about weather conditions and holidays is available.                             │
│                                                                                 │
│ Source:                                                                         │
│ Fanaee-T,Hadi. (2013). Bike Sharing Dataset. UCI Machine Learning Repository.   │
│ https://doi.org/10.24432/C5W894.                                                │
│                                                                                 │
│ URL:                                                                            │
│ https://raw.githubusercontent.com/skforecast/skforecast-                        │
│ datasets/main/data/bike_sharing_dataset_clean.csv                               │
│                                                                                 │
│ Shape: 17544 rows x 12 columns                                                  │
╰─────────────────────────────────────────────────────────────────────────────────╯
| date_time | users | holiday | weather | temp | |
|---|---|---|---|---|---|
| 0 | 2011-01-01 00:00:00 | 16.0 | 0.0 | clear | 9.84 |
| 1 | 2011-01-01 01:00:00 | 40.0 | 0.0 | clear | 9.02 |
| 2 | 2011-01-01 02:00:00 | 32.0 | 0.0 | clear | 9.02 |
| 3 | 2011-01-01 03:00:00 | 13.0 | 0.0 | clear | 9.84 |
| 4 | 2011-01-01 04:00:00 | 1.0 | 0.0 | clear | 9.84 |
✏️ Note
skforecast-ai is ready to preprocess the data, but it is recommended that users apply their own preprocessing steps before using the assistant. This ensures the data is in the desired format and any necessary transformations have been applied before proceeding with the forecasting workflow.
# Interactive plot of time series
# ==============================================================================
fig = go.Figure()
fig.add_trace(
    go.Scatter(x=data['date_time'], y=data['users'], mode='lines', name='Users')
)
fig.update_layout(
    title  = 'Number of users',
    xaxis_title="Time",
    yaxis_title="Users",
    width=800,
    height=400,
    margin=dict(l=20, r=20, t=35, b=20),
    legend=dict(orientation="h", yanchor="top", y=1, xanchor="left", x=0.001)
)
fig.show()
For a deeper walkthrough of the exploratory analysis behind this dataset, see the skforecast example: Forecasting time series with skforecast, XGBoost, LightGBM and CatBoost.
Profile the data
The profile() method is the first stage of the step-by-step workflow. It inspects the dataset and returns a ForecastingProfile object that contains:
Data metadata: detected frequency, index type, series lengths, missing values, and exogenous column roles.
Modeling recommendations: the selected forecaster family and estimator, along with alternative candidates and the reasoning behind each choice.
Lag structure: PACF-significant lags per series, used as a baseline for the planning stage.
Window feature suggestions: rolling statistics configurations appropriate for the seasonal periods implied by the frequency.
This is a purely deterministic step: no LLM is involved. The profile object is a prerequisite for plan(), and can be passed to ask() as context to have its decisions explained.
| Attribute | Description |
|---|---|
data_profile |
Full dataset metadata: frequency, index type, series lengths, missing values, exog columns |
task_type |
Family of the recommendation: 'single_series', 'multi_series', 'multivariate', 'statistical' or 'foundation' |
forecaster |
Recommended skforecast forecaster class name |
forecaster_candidates |
Ordered list of compatible forecaster names |
estimator |
Recommended estimator: a scikit-learn compatible estimator name, 'Arima' for statistical tasks, or the Hugging Face model ID of the foundation model |
estimator_candidates |
Ordered list of compatible estimator names |
series_pacf |
Per-series PACF-significant lags (used by plan() to set default lags) |
window_features |
Suggested window feature configurations |
calendar_features |
Recommended calendar feature names derived from the frequency |
explanation |
Human-readable explanation of why this forecaster and estimator were selected |
# Profile the data
# ==============================================================================
profile = assistant.profile(
    data        = data,
    target      = 'users',
    date_column = 'date_time'
)
# Inspect the profile
# ==============================================================================
profile
                          Dataset Profile
┏━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Property       ┃ Value                                          ┃
┡━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ Format         │ single                                         │
├────────────────┼────────────────────────────────────────────────┤
│ Series         │ 1                                              │
├────────────────┼────────────────────────────────────────────────┤
│ Observations   │ 17544                                          │
├────────────────┼────────────────────────────────────────────────┤
│ Frequency      │ h                                              │
├────────────────┼────────────────────────────────────────────────┤
│ Target         │ users                                          │
├────────────────┼────────────────────────────────────────────────┤
│ Exog columns   │ holiday, weather, temp  (categorical: weather) │
├────────────────┼────────────────────────────────────────────────┤
│ Missing values │ None                                           │
└────────────────┴────────────────────────────────────────────────┘

                                    Recommendation
┏━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Property              ┃ Value                                                       ┃
┡━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ Task type             │ single_series                                               │
├───────────────────────┼─────────────────────────────────────────────────────────────┤
│ Forecaster            │ ForecasterRecursive                                         │
├───────────────────────┼─────────────────────────────────────────────────────────────┤
│ Forecaster candidates │ ForecasterRecursive, ForecasterDirect, ForecasterFoundation │
├───────────────────────┼─────────────────────────────────────────────────────────────┤
│ Estimator             │ LGBMRegressor                                               │
├───────────────────────┼─────────────────────────────────────────────────────────────┤
│ Estimator candidates  │ LGBMRegressor, XGBRegressor, Ridge                          │
└───────────────────────┴─────────────────────────────────────────────────────────────┘

╭───────────────────────────────── Profile Explanation ──────────────────────────────────╮
│                                                                                        │
│  A single-series ML forecaster (ForecasterRecursive) is recommended. Data: 17544       │
│  observations, 'h' frequency. Alternative forecasters: ['ForecasterDirect',            │
│  'ForecasterFoundation']. Estimator: LGBMRegressor. A gradient boosting model is       │
│  preferred for a dataset of this size (17544 observations). Alternative estimators:    │
│  ['XGBRegressor', 'Ridge']. 3 exogenous variables (1 categorical) available as         │
│  predictors.                                                                           │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
Every result also has a describe() method. It returns a plain-text description of the object, built by rules, without calling an LLM. It is also what ask() sends to the LLM about that object, so you can read it before asking.
# Plain-text description of the profile (no LLM involved)
# ==============================================================================
print(profile.describe())
<forecast_context>
<dataset>
- Observations: 17544
- Series: 1
- Frequency: h
- Date range: 2011-01-01 to 2012-12-31 23:00:00
- Target: users
- Exogenous columns: holiday, weather, temp
- Categorical exogenous columns: weather
- Target statistics: min 1, max 977, mean 187.8, std 181.3
- Missing values: none
- Index irregularities: none detected
</dataset>
<profile_decision>
A single-series ML forecaster (ForecasterRecursive) is recommended. Data: 17544 observations, 'h' frequency. Alternative forecasters: ['ForecasterDirect', 'ForecasterFoundation']. Estimator: LGBMRegressor. A gradient boosting model is preferred for a dataset of this size (17544 observations). Alternative estimators: ['XGBRegressor', 'Ridge']. 3 exogenous variables (1 categorical) available as predictors.
- Significant lags (partial autocorrelation, strongest first): 1, 2, 23, 22, 25, 169, 10, 145, 17, 143, 167, 19, 21, 337, 3 (first 15 of 32)
- Suggested window features: mean(window=3), std(window=3), mean(window=24), mean(window=168)
- Suggested calendar features: hour, day_of_week, weekend, month
</profile_decision>
</forecast_context>
Once you have a profile, you can pass it to ask() as context to get an LLM-generated explanation of the modeling decisions. No plan is involved yet: the LLM only sees the dataset summary and the profile decisions.
Each call briefs the model with a set of skills, curated skforecast documents chosen from the context and the wording of the question, so the answer follows the current skforecast API. See Skills for the LLM for the list and how to choose them yourself.
# Ask the assistant to explain the profile
# ==============================================================================
answer = assistant.ask(
    prompt  = (
        "Explain why this forecaster and estimator were recommended for my "
        "hourly bike-sharing demand data, and what the exogenous variables add."
    ),
    context = profile,
)
answer.show_explanation()
╭────────────────────────────────── Assistant Response ──────────────────────────────────╮
│                                                                                        │
│  ForecasterRecursive with LGBMRegressor was recommended because the dataset consists   │
│  of a single hourly series with 17544 observations, making gradient boosting well      │
│  suited for learning nonlinear patterns at this scale. The exogenous variables         │
│  provide external contextual signals that may be associated with hourly changes in     │
│  rider demand.                                                                         │
│                                                                                        │
│  Forecaster Recommendation                                                             │
│                                                                                        │
│   • Model type: ForecasterRecursive is recommended as the single-series machine        │
│     learning forecaster for the continuous target users across 17544 observations at   │
│     frequency h.                                                                       │
│   • Multi-step approach: It trains a single model that recursively feeds predictions   │
│     into future steps, accommodating the autoregressive structure identified across    │
│     the series.                                                                        │
│   • Alternatives noted: The profile decision identifies ForecasterDirect and           │
│     ForecasterFoundation as alternative forecaster choices.                            │
│                                                                                        │
│  Estimator Recommendation                                                              │
│                                                                                        │
│   • Gradient boosting preference: LGBMRegressor is preferred for a dataset of 17544    │
│     observations, where gradient boosted trees handle feature interactions             │
│     efficiently without requiring deep model architectures.                            │
│   • Categorical compatibility: LGBMRegressor natively supports categorical predictors  │
│     such as the weather variable without requiring extensive manual preprocessing.     │
│   • Alternatives noted: The profile decision lists XGBRegressor and Ridge as           │
│     alternative estimators.                                                            │
│                                                                                        │
│  Role of Exogenous Variables                                                           │
│                                                                                        │
│   • Predictor set: The data provides 3 exogenous variables: holiday, weather, and      │
│     temp.                                                                              │
│   • Categorical variable: weather is designated as a categorical exogenous column,     │
│     capturing distinct conditions.                                                     │
│   • External factors: These variables supply environmental and calendar context that   │
│     may contribute to predicting demand, operating alongside the 32 identified lag     │
│     values, rolling window features, and calendar features.                            │
│   • Attribution limit: Feature importances are not provided, so the exact predictive   │
│     contribution or ranking of these exogenous variables cannot be measured.           │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
Build the plan
The plan() method converts the coarse modeling decisions in the ForecastingProfile into a fully-specified, executable configuration. It determines:
- Lags: derived from the PACF-significant lags detected in the profile. You can override these explicitly.
- Window features: rolling statistics configurations appropriate for the seasonal periods implied by the frequency.
- Preprocessing steps: ordered list of data preparation actions (e.g., handling missing values, gaps or categorical exogenous variables).
- Prediction interval method:
'bootstrapping','conformal', or'native'(selected based on the forecaster). - Metrics: the primary and secondary evaluation metrics.
Like profile(), this is a deterministic step. The resulting ForecastPlan object is the complete blueprint that forecast() and backtest() execute.
| Attribute | Description |
|---|---|
task_type |
Family of the plan, as in the profile, plus 'baseline' for ForecasterEquivalentDate |
forecaster |
Forecaster class name |
estimator |
Estimator class name; the Hugging Face model ID for ForecasterFoundation; None for ForecasterEquivalentDate |
forecaster_kwargs |
All constructor kwargs for the forecaster, including lags and window_features |
estimator_kwargs |
Constructor kwargs for the estimator |
steps |
Forecast horizon |
interval |
Prediction interval quantiles, e.g. [0.1, 0.9] |
interval_method |
Method used to produce the interval (bootstrapping, conformal, or native) |
metric |
Primary metric, used to rank a comparison |
use_exog |
Whether exogenous variables are included |
overridden_fields |
Decisions you made instead of the rules; empty when every value comes from the rules |
preprocessing_steps |
Ordered list of preprocessing actions with code snippets |
explanation |
Human-readable explanation of plan decisions |
# Build a plan from the profile
# ==============================================================================
plan = assistant.plan(
    profile  = profile,
    steps    = 36,
    interval = [0.1, 0.9]  # 80% prediction interval
)
# Inspect the plan
# ==============================================================================
plan
                                      Forecast Plan
┏━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Property          ┃ Value                                                              ┃
┡━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ Task type         │ single_series                                                      │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Forecaster        │ ForecasterRecursive                                                │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Estimator         │ LGBMRegressor                                                      │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Steps             │ 36                                                                 │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Frequency         │ h                                                                  │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Lags              │ [1, 2, 3, 5, 8, 10, 15, 17, 19, 20, 21, 22, 23, 24, 25, 26, 32,    │
│                   │ 33, 119, 121, 135, 136, 142, 143, 145, 160, 166, 167, 169, 313,    │
│                   │ 335, 337]                                                          │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Window features   │ [{'stats': ['mean', 'std'], 'window_size': 3}, {'stats': ['mean'], │
│                   │ 'window_size': 24}, {'stats': ['mean'], 'window_size': 168}]       │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Calendar features │ ['hour', 'day_of_week', 'weekend', 'month'] (raw ordinal encoding) │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Use exog          │ True                                                               │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Interval          │ [0.1, 0.9]                                                         │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Interval method   │ bootstrapping                                                      │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Primary metric    │ mean_absolute_error                                                │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Preprocessing     │ 1 step                                                             │
└───────────────────┴────────────────────────────────────────────────────────────────────┘

                                   Preprocessing Steps
┏━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Step                    ┃ Reason                                                       ┃
┡━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ handle_categorical_exog │ Categorical exogenous variables detected: ['weather']. These │
│                         │ are handled automatically by skforecast                      │
│                         │ (categorical_features='auto').                               │
└─────────────────────────┴──────────────────────────────────────────────────────────────┘

╭─────────────────────────────────── Plan Explanation ───────────────────────────────────╮
│                                                                                        │
│  Plan: ForecasterRecursive + LGBMRegressor. Lags: [1, 2, 3, 5, 8, 10, 15, 17, 19, 20,  │
│  21, 22, 23, 24, 25, 26, 32, 33, 119, 121, 135, 136, 142, 143, 145, 160, 166, 167,     │
│  169, 313, 335, 337]. Window features: ['mean(window=3)', 'std(window=3)',             │
│  'mean(window=24)', 'mean(window=168)']. Calendar features: ['hour', 'day_of_week',    │
│  'weekend', 'month'] (raw ordinal encoding). Prediction intervals via bootstrapping.   │
│  Exogenous variables included. MAE is interpretable, robust to outliers, and works at  │
│  any scale.                                                                            │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
Pass the profile as context together with the plan for a detailed explanation of the chosen configuration. The two are rendered into the same script forecast_code() would produce: answer.code returns it, and the LLM receives a description of it (never the script itself).
# Ask the assistant to explain the plan
# ==============================================================================
answer = assistant.ask(
    prompt  = (
        "Walk me through this plan. Why these lags and window features, "
        "and how will the 80% prediction interval be produced?"
    ),
    context = profile,
    plan    = plan,
)
answer.show_explanation()
╭────────────────────────────────── Assistant Response ──────────────────────────────────╮
│                                                                                        │
│  The forecast plan configures a ForecasterRecursive model with LGBMRegressor to        │
│  generate 36 hourly forecasts for the users series. The design uses 32 specific lags   │
│  alongside rolling window statistics and calendar features to represent the series     │
│  dynamics across multiple horizons. The 80% prediction interval is generated via       │
│  residual bootstrapping using lower and upper percentiles.                             │
│                                                                                        │
│  Plan Overview                                                                         │
│                                                                                        │
│   • Forecaster: ForecasterRecursive with an LGBMRegressor estimator.                   │
│   • Horizon: 36 steps ahead.                                                           │
│   • Exogenous inputs: holiday, weather, and temp, where weather is categorical and     │
│     handled via categorical_features='auto'.                                           │
│   • Calendar features: hour, day_of_week, weekend, and month using raw ordinal         │
│     encoding.                                                                          │
│   • Primary evaluation metric: mean_absolute_error.                                    │
│                                                                                        │
│  Lags and Window Features                                                              │
│                                                                                        │
│   • Lag selection: The plan includes 32 lags: [1, 2, 3, 5, 8, 10, 15, 17, 19, 20, 21,  │
│     22, 23, 24, 25, 26, 32, 33, 119, 121, 135, 136, 142, 143, 145, 160, 166, 167,      │
│     169, 313, 335, 337].                                                               │
│   • Autocorrelation basis: These lags originate from the dataset profile, which        │
│     identified significant partial autocorrelation structure. The strongest partial    │
│     autocorrelation values appeared at lags 1, 2, 23, 22, 25, 169, 10, 145, 17, 143,   │
│     167, 19, 21, 337, and 3.                                                           │
│   • Window features: Three sets of rolling features are configured:                    │
│      • Window size 3: mean and std.                                                    │
│      • Window size 24: mean.                                                           │
│      • Window size 168: mean.                                                          │
│   • Window scope: These statistics aggregate behavior over the immediate short term    │
│     (3 hours), a daily cycle (24 hours), and a weekly cycle (168 hours).               │
│                                                                                        │
│  Prediction Interval Calculation                                                       │
│                                                                                        │
│   • Target interval: An 80% prediction interval spanning the quantiles [0.1, 0.9].     │
│   • Method: Bootstrapping.                                                             │
│   • Procedure: During model fitting, residuals are collected. In recursive             │
│     prediction, bootstrap samples are drawn with replacement from these residuals and  │
│     applied across the 36-step trajectory, creating simulated paths from which the     │
│     10th and 90th percentiles are extracted as interval bounds.                        │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
Refine the plan (optional)
The refine_plan() method lets you adjust the plan before execution. It operates in two distinct modes:
Deterministic mode (
prompt=None): pass explicit configuration overrides such aslags,estimator,estimator_kwargs,forecaster,steps,interval, orwindow_features. Only the fields you explicitly specify are updated; the rest of the configuration is deterministically re-derived from the original plan.LLM mode (
promptprovided): describe your domain knowledge in natural language. The LLM interprets this context and suggests appropriatelagsandwindow_features. Its reasoning is appended toplan.explanationand the changed fields are recorded inplan.llm_refined_fieldsfor full traceability. It applies to the machine learning forecasters:ForecasterStats,ForecasterFoundationandForecasterEquivalentDateuse no lags or window features, so for them the prompt is ignored with a warning and the LLM is not called.
The Agentic forecasting guide shows in an animation what the LLM receives in LLM mode, and how a suggestion is validated before it enters the plan.
⚠ Warning
A refined plan is a hypothesis, not a guaranteed improvement. The LLM may propose lags or window features that are not helpful for the series, or it may misread the domain context you provided. Always compare the refined plan against the original baseline using a proper backtest over multiple folds before adopting it.
Deterministic mode
# Refine the plan with explicit overrides (no LLM required)
# ==============================================================================
plan_det = assistant.refine_plan(
    profile          = profile,
    plan             = plan,
    lags             = [1, 2, 3, 24, 48, 168],
    estimator_kwargs = {'n_estimators': 200, 'max_depth': 6},
    metric           = 'mean_absolute_scaled_error'
)
plan_det
                                      Forecast Plan
┏━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Property          ┃ Value                                                              ┃
┡━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ Task type         │ single_series                                                      │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Forecaster        │ ForecasterRecursive                                                │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Estimator         │ LGBMRegressor                                                      │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Steps             │ 36                                                                 │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Frequency         │ h                                                                  │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Lags              │ [1, 2, 3, 24, 48, 168]                                             │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Window features   │ [{'stats': ['mean', 'std'], 'window_size': 3}, {'stats': ['mean'], │
│                   │ 'window_size': 24}, {'stats': ['mean'], 'window_size': 168}]       │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Calendar features │ ['hour', 'day_of_week', 'weekend', 'month'] (raw ordinal encoding) │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Use exog          │ True                                                               │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Interval          │ [0.1, 0.9]                                                         │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Interval method   │ bootstrapping                                                      │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Primary metric    │ mean_absolute_scaled_error                                         │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Preprocessing     │ 1 step                                                             │
└───────────────────┴────────────────────────────────────────────────────────────────────┘

                                   Preprocessing Steps
┏━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Step                    ┃ Reason                                                       ┃
┡━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ handle_categorical_exog │ Categorical exogenous variables detected: ['weather']. These │
│                         │ are handled automatically by skforecast                      │
│                         │ (categorical_features='auto').                               │
└─────────────────────────┴──────────────────────────────────────────────────────────────┘

╭─────────────────────────────────── Plan Explanation ───────────────────────────────────╮
│                                                                                        │
│  Plan: ForecasterRecursive + LGBMRegressor. Lags: [1, 2, 3, 24, 48, 168]. Window       │
│  features: ['mean(window=3)', 'std(window=3)', 'mean(window=24)',                      │
│  'mean(window=168)']. Calendar features: ['hour', 'day_of_week', 'weekend', 'month']   │
│  (raw ordinal encoding). Prediction intervals via bootstrapping. Exogenous variables   │
│  included. Metric: mean_absolute_scaled_error, as requested.                           │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
metric is one of the arguments that choose a decision instead of the rule. The others are use_exog, differentiation, calendar_features, target_transformer and dropna_from_series, and plan() accepts them too. overridden_fields names the decisions you made, so the plan always tells your choices from the ones of the rules.
# Decisions made by the user instead of the rules
# ==============================================================================
plan_det.overridden_fields
['estimator_kwargs', 'lags', 'metric']
LLM mode
# Refine the plan using LLM-guided domain knowledge
# ==============================================================================
prompt = (
    "I'm forecasting hourly bike rentals. Demand follows a clear daily rhythm with "
    "rush-hour peaks, and it changes between weekdays and weekends. It's also usually "
    "similar to what happened at the same time last week, and the last few hours give "
    "a good sense of the current trend. Please pick lags and rolling features that fit this."
)

plan_refined = assistant.refine_plan(
    profile = profile,
    plan    = plan,
    prompt  = prompt
)
# Refined plan proposed by the assistant
# ==============================================================================
plan_refined
                                      Forecast Plan
┏━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Property          ┃ Value                                                              ┃
┡━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ Task type         │ single_series                                                      │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Forecaster        │ ForecasterRecursive                                                │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Estimator         │ LGBMRegressor                                                      │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Steps             │ 36                                                                 │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Frequency         │ h                                                                  │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Lags              │ [1, 2, 3, 4, 23, 24, 25, 47, 48, 167, 168, 169]  (LLM-suggested)   │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Window features   │ [{'stats': ['mean', 'std'], 'window_size': 4}, {'stats': ['mean',  │
│                   │ 'max'], 'window_size': 24}, {'stats': ['mean'], 'window_size':     │
│                   │ 168}]  (LLM-suggested)                                             │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Calendar features │ ['hour', 'day_of_week', 'weekend', 'month'] (raw ordinal encoding) │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Use exog          │ True                                                               │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Interval          │ [0.1, 0.9]                                                         │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Interval method   │ bootstrapping                                                      │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Primary metric    │ mean_absolute_error                                                │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Preprocessing     │ 1 step                                                             │
└───────────────────┴────────────────────────────────────────────────────────────────────┘

                                   Preprocessing Steps
┏━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Step                    ┃ Reason                                                       ┃
┡━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ handle_categorical_exog │ Categorical exogenous variables detected: ['weather']. These │
│                         │ are handled automatically by skforecast                      │
│                         │ (categorical_features='auto').                               │
└─────────────────────────┴──────────────────────────────────────────────────────────────┘

╭─────────────────────────────────── Plan Explanation ───────────────────────────────────╮
│                                                                                        │
│  Plan: ForecasterRecursive + LGBMRegressor. Lags: [1, 2, 3, 4, 23, 24, 25, 47, 48,     │
│  167, 168, 169]. Window features: ['mean(window=4)', 'std(window=4)',                  │
│  'mean(window=24)', 'max(window=24)', 'mean(window=168)']. Calendar features:          │
│  ['hour', 'day_of_week', 'weekend', 'month'] (raw ordinal encoding). Prediction        │
│  intervals via bootstrapping. Exogenous variables included. MAE is interpretable,      │
│  robust to outliers, and works at any scale.                                           │
│                                                                                        │
│  LLM Refinement Reasoning: To capture the hourly bike rental dynamics described:       │
│                                                                                        │
│   • Lags 1 to 4 capture short-term autoregressive momentum and the recent hourly       │
│     trend.                                                                             │
│   • Lags 23, 24, 25, 47, and 48 capture daily periodicity (24 hours and 48 hours       │
│     prior) along with adjacent hourly shifts around daily rush hours.                  │
│   • Lags 167, 168, and 169 capture weekly seasonality (168 hours = 7 days), ensuring   │
│     the model aligns with the corresponding hour and day of the previous week          │
│     (differentiating weekday and weekend patterns).                                    │
│   • Rolling features across a 4-hour window (mean and standard deviation) capture      │
│     immediate trend and short-term demand variability.                                 │
│   • A 24-hour rolling window (mean and max) captures daily baseline demand and peak    │
│     rush-hour intensity.                                                               │
│   • A 168-hour rolling mean tracks weekly baseline level shifts.                       │
│                                                                                        │
│  Note: the LLM-suggested lags and window_features are hypotheses, not validated        │
│  improvements. Confirm any expected accuracy gain before relying on them.              │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
Explain mode (refined plan)
# Ask the assistant what changed and why
# ==============================================================================
answer = assistant.ask(
    prompt  = (
        "What changed in the refined plan compared to the original, "
        "and why does it matter for this dataset?"
    ),
    context = profile,
    plan    = plan_refined,
)
answer.show_explanation()
╭────────────────────────────────── Assistant Response ──────────────────────────────────╮
│                                                                                        │
│  The refined plan updates the feature engineering setup by specifying a targeted lag   │
│  structure and adjusting the rolling window features. These changes aim to capture     │
│  multi-scale patterns in the hourly dataset, specifically short-term momentum, daily   │
│  cycles, and weekly seasonality.                                                       │
│                                                                                        │
│  Changes in the Refined Plan                                                           │
│                                                                                        │
│   • Lags: The original profile identified significant partial autocorrelation lags     │
│     (such as 1, 2, 23, 22, 25, 169, and others), whereas the refined plan selects a    │
│     specific subset: [1, 2, 3, 4, 23, 24, 25, 47, 48, 167, 168, 169].                  │
│   • Window features: The initial profile suggested mean(window=3), std(window=3),      │
│     mean(window=24), and mean(window=168). The refined plan adjusts the short window   │
│     from size 3 to size 4 with mean and std, adds max alongside mean for window size   │
│     24, and retains the 168-hour rolling mean.                                         │
│   • Unchanged components: The forecaster type (ForecasterRecursive), estimator         │
│     (LGBMRegressor), calendar features (hour, day_of_week, weekend, month), and        │
│     exogenous variables (holiday, weather, temp) remain the same.                      │
│                                                                                        │
│  Why These Adjustments Matter for the Dataset                                          │
│                                                                                        │
│   • Short-term dynamics: Lags 1 to 4 and the 4-hour rolling mean and standard          │
│     deviation capture recent hourly momentum, short-term demand variability, and       │
│     immediate trends.                                                                  │
│   • Daily periodicity: Lags 23, 24, 25, 47, and 48 cover 24-hour and 48-hour cycles    │
│     along with adjacent hours around daily rush hours. The 24-hour rolling window      │
│     with mean and max captures daily baseline demand and peak rush-hour intensity.     │
│   • Weekly seasonality: Lags 167, 168, and 169 (where 168 hours equals 7 days) and     │
│     the 168-hour rolling mean align predictions with the corresponding day and hour    │
│     of the prior week, distinguishing weekday from weekend patterns and tracking       │
│     weekly baseline shifts.                                                            │
│                                                                                        │
│  Note that the refined lags and window features are hypotheses rather than validated   │
│  improvements. You can evaluate their performance against alternative configurations   │
│  by running assistant.backtest() or comparing setups using assistant.compare().        │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
Forecast
Once you have a profile and a plan, you can call forecast() or forecast_code(). Both accept the pre-computed profile and plan so no additional profiling is performed. The forecast() method executes the generated script and returns a ForecastResult; forecast_code() generates the script only, without running it.
The forecast branch operates in two modes:
Evaluation mode (
test_sizeis set): the dataset is split into train and test sets, the model is trained on the train portion, and predictions are compared against the held-out actuals to compute metrics.Prediction mode (
test_size=None, the default): the model is trained on the entire dataset and forecasts the nextstepstime points into the future. Because there is no ground truth, no metrics are returned. If the plan uses exogenous variables, their future values must be supplied viaexog.
Evaluation mode
# Forecast in evaluation mode, reusing the pre-computed profile and plan
# ==============================================================================
results_eval = assistant.forecast(
    data        = data,
    steps       = 36,
    interval    = [0.1, 0.9],   # 80% prediction interval
    test_size   = 36,           # Last 36 hours as test set
    profile     = profile,      # Reuse the pre-computed profile
    plan        = plan_refined  # Reuse the refined plan
)

display(results_eval.metrics)
display(results_eval.predictions.head())
| series | MAE | MSE | MASE | MAPE | |
|---|---|---|---|---|---|
| 0 | users | 46.542601 | 4757.93798 | 0.722832 | 0.470479 |
| pred | lower_bound | upper_bound | |
|---|---|---|---|
| 2012-12-30 12:00:00 | 150.140531 | 119.962576 | 180.806519 |
| 2012-12-30 13:00:00 | 131.285497 | 93.529479 | 175.605520 |
| 2012-12-30 14:00:00 | 129.158744 | 92.731312 | 171.324671 |
| 2012-12-30 15:00:00 | 130.043044 | 94.448394 | 168.117601 |
| 2012-12-30 16:00:00 | 137.809651 | 92.988786 | 174.743751 |
# Plot predictions vs. actual values for the held-out test period
# ==============================================================================
set_dark_theme()
preds = results_eval.predictions
fig, ax = plt.subplots(figsize=(7, 3.5))
data.set_index('date_time').loc[preds.index, 'users'].plot(ax=ax, label='actual')
preds['pred'].plot(ax=ax, label='prediction')
if {'lower_bound', 'upper_bound'}.issubset(preds.columns):
    ax.fill_between(
        preds.index, preds['lower_bound'], preds['upper_bound'],
        alpha=0.3, label='80% prediction interval'
    )
ax.set_title('Predictions vs. actual bike demand')
ax.set_ylabel('Users')
ax.legend()
plt.tight_layout()
plt.show()

# Ask the assistant to interpret the forecast results
# ==============================================================================
answer = assistant.ask(
    prompt  = "Explain the results of this forecast, including the metrics and predictions.",
    context = results_eval
)
answer.show_explanation()
/var/folders/wt/8tvn563d5v55nspfbydgqb9r0000gp/T/ipykernel_71015/3255811032.py:3: DataSentToLLMWarning: `send_data_to_llm=False` does not apply to `context`: the predicted values it carries are sent to the LLM, because a question about a result cannot be answered from summary statistics alone. Your input data is not sent: a result holds only the model's output, never the data it was fitted on. To keep predictions local, ask without `context`.
  answer = assistant.ask(
╭────────────────────────────────── Assistant Response ──────────────────────────────────╮
│                                                                                        │
│  The 36-step forecast for the users series was generated using ForecasterRecursive     │
│  with LGBMRegressor, producing point predictions alongside an 80% bootstrapping        │
│  prediction interval. The model achieved a Mean Absolute Error of 46.542601 and a      │
│  Mean Absolute Scaled Error of 0.722832 on evaluation. Across the 36 forecast steps,   │
│  the predicted values average 67.64379275041186.                                       │
│                                                                                        │
│  Evaluation Metrics                                                                    │
│                                                                                        │
│  The model evaluation produced the following metrics:                                  │
│                                                                                        │
│   • MAE: 46.542601                                                                     │
│   • MSE: 4757.93798                                                                    │
│   • MASE: 0.722832. Because this value is below 1, the model beats the one-step naive  │
│     forecast (last training value).                                                    │
│   • MAPE: 0.470479. MAPE represents a percentage error; note that it becomes           │
│     unreliable as the target approaches zero, and the dataset target minimum is 1.     │
│                                                                                        │
│  Prediction Summary                                                                    │
│                                                                                        │
│  The forecast covers 36 hourly steps from 2012-12-30 12:00:00 to 2012-12-31 23:00:00,  │
│  accompanied by lower and upper bounds corresponding to the [0.1, 0.9] interval.       │
│  Across all 36 steps:                                                                  │
│                                                                                        │
│   • Point predictions (pred): minimum of 3.2108862522441286, maximum of                │
│     158.6940989915074, and mean of 67.64379275041186.                                  │
│   • Lower bound: minimum of -1.021796684480627, maximum of 119.96257558258043, and     │
│     mean of 40.46442222067216.                                                         │
│   • Upper bound: minimum of 9.56485040531428, maximum of 184.70997640284222, and mean  │
│     of 102.6152088255848.                                                              │
│                                                                                        │
│  Because intermediate rows are omitted, overall progressions or horizon-wide trends    │
│  cannot be evaluated beyond these summary statistics.                                  │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
Prediction mode
In prediction mode, the model trains on the entire dataset and forecasts the next steps time points. Because the data includes exogenous variables (holiday, weather, temp), their future values must be supplied via the exog argument.
# Forecast the next 36 hours using the entire dataset (prediction mode)
# ==============================================================================
# Simulate future values of exogenous variables for the next 36 hours
exog = data[['holiday', 'weather', 'temp']].tail(36).copy()
exog.index = pd.date_range(
    start=pd.to_datetime(data['date_time'].max()) + pd.Timedelta(1, unit='h'),
    periods=36,
    freq='h'
)

results_pred = assistant.forecast(
    data        = data,
    steps       = 36,
    interval    = [0.1, 0.9],
    test_size   = None,        # Use the entire dataset (prediction mode)
    exog        = exog,        # Future values of exogenous variables
    profile     = profile,
    plan        = plan_refined
)

display(results_pred.predictions.head())
| pred | lower_bound | upper_bound | |
|---|---|---|---|
| 2013-01-01 00:00:00 | 21.581406 | 13.059198 | 31.121462 |
| 2013-01-01 01:00:00 | 10.182992 | 3.921566 | 19.012760 |
| 2013-01-01 02:00:00 | 6.319521 | 2.408637 | 12.343762 |
| 2013-01-01 03:00:00 | 6.074862 | 1.447885 | 10.981221 |
| 2013-01-01 04:00:00 | 6.074862 | 1.931540 | 12.771343 |
# Full results object
# ==============================================================================
results_pred
                          Dataset Profile
┏━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Property       ┃ Value                                          ┃
┡━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ Format         │ single                                         │
├────────────────┼────────────────────────────────────────────────┤
│ Series         │ 1                                              │
├────────────────┼────────────────────────────────────────────────┤
│ Observations   │ 17544                                          │
├────────────────┼────────────────────────────────────────────────┤
│ Frequency      │ h                                              │
├────────────────┼────────────────────────────────────────────────┤
│ Target         │ users                                          │
├────────────────┼────────────────────────────────────────────────┤
│ Exog columns   │ holiday, weather, temp  (categorical: weather) │
├────────────────┼────────────────────────────────────────────────┤
│ Missing values │ None                                           │
└────────────────┴────────────────────────────────────────────────┘

                                    Recommendation
┏━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Property              ┃ Value                                                       ┃
┡━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ Task type             │ single_series                                               │
├───────────────────────┼─────────────────────────────────────────────────────────────┤
│ Forecaster            │ ForecasterRecursive                                         │
├───────────────────────┼─────────────────────────────────────────────────────────────┤
│ Forecaster candidates │ ForecasterRecursive, ForecasterDirect, ForecasterFoundation │
├───────────────────────┼─────────────────────────────────────────────────────────────┤
│ Estimator             │ LGBMRegressor                                               │
├───────────────────────┼─────────────────────────────────────────────────────────────┤
│ Estimator candidates  │ LGBMRegressor, XGBRegressor, Ridge                          │
└───────────────────────┴─────────────────────────────────────────────────────────────┘

╭───────────────────────────────── Profile Explanation ──────────────────────────────────╮
│                                                                                        │
│  A single-series ML forecaster (ForecasterRecursive) is recommended. Data: 17544       │
│  observations, 'h' frequency. Alternative forecasters: ['ForecasterDirect',            │
│  'ForecasterFoundation']. Estimator: LGBMRegressor. A gradient boosting model is       │
│  preferred for a dataset of this size (17544 observations). Alternative estimators:    │
│  ['XGBRegressor', 'Ridge']. 3 exogenous variables (1 categorical) available as         │
│  predictors.                                                                           │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
                                      Forecast Plan
┏━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Property          ┃ Value                                                              ┃
┡━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ Task type         │ single_series                                                      │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Forecaster        │ ForecasterRecursive                                                │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Estimator         │ LGBMRegressor                                                      │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Steps             │ 36                                                                 │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Frequency         │ h                                                                  │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Lags              │ [1, 2, 3, 4, 23, 24, 25, 47, 48, 167, 168, 169]  (LLM-suggested)   │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Window features   │ [{'stats': ['mean', 'std'], 'window_size': 4}, {'stats': ['mean',  │
│                   │ 'max'], 'window_size': 24}, {'stats': ['mean'], 'window_size':     │
│                   │ 168}]  (LLM-suggested)                                             │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Calendar features │ ['hour', 'day_of_week', 'weekend', 'month'] (raw ordinal encoding) │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Use exog          │ True                                                               │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Interval          │ [0.1, 0.9]                                                         │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Interval method   │ bootstrapping                                                      │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Primary metric    │ mean_absolute_error                                                │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Preprocessing     │ 1 step                                                             │
└───────────────────┴────────────────────────────────────────────────────────────────────┘

                                   Preprocessing Steps
┏━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Step                    ┃ Reason                                                       ┃
┡━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ handle_categorical_exog │ Categorical exogenous variables detected: ['weather']. These │
│                         │ are handled automatically by skforecast                      │
│                         │ (categorical_features='auto').                               │
└─────────────────────────┴──────────────────────────────────────────────────────────────┘

╭─────────────────────────────────── Plan Explanation ───────────────────────────────────╮
│                                                                                        │
│  Plan: ForecasterRecursive + LGBMRegressor. Lags: [1, 2, 3, 4, 23, 24, 25, 47, 48,     │
│  167, 168, 169]. Window features: ['mean(window=4)', 'std(window=4)',                  │
│  'mean(window=24)', 'max(window=24)', 'mean(window=168)']. Calendar features:          │
│  ['hour', 'day_of_week', 'weekend', 'month'] (raw ordinal encoding). Prediction        │
│  intervals via bootstrapping. Exogenous variables included. MAE is interpretable,      │
│  robust to outliers, and works at any scale.                                           │
│                                                                                        │
│  LLM Refinement Reasoning: To capture the hourly bike rental dynamics described:       │
│                                                                                        │
│   • Lags 1 to 4 capture short-term autoregressive momentum and the recent hourly       │
│     trend.                                                                             │
│   • Lags 23, 24, 25, 47, and 48 capture daily periodicity (24 hours and 48 hours       │
│     prior) along with adjacent hourly shifts around daily rush hours.                  │
│   • Lags 167, 168, and 169 capture weekly seasonality (168 hours = 7 days), ensuring   │
│     the model aligns with the corresponding hour and day of the previous week          │
│     (differentiating weekday and weekend patterns).                                    │
│   • Rolling features across a 4-hour window (mean and standard deviation) capture      │
│     immediate trend and short-term demand variability.                                 │
│   • A 24-hour rolling window (mean and max) captures daily baseline demand and peak    │
│     rush-hour intensity.                                                               │
│   • A 168-hour rolling mean tracks weekly baseline level shifts.                       │
│                                                                                        │
│  Note: the LLM-suggested lags and window_features are hypotheses, not validated        │
│  improvements. Confirm any expected accuracy gain before relying on them.              │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
                    Predictions (36 rows)
┏━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━┳━━━━━━━━━━━━━┳━━━━━━━━━━━━━┓
┃ Index               ┃    pred ┃ lower_bound ┃ upper_bound ┃
┡━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━╇━━━━━━━━━━━━━╇━━━━━━━━━━━━━┩
│ 2013-01-01 00:00:00 │ 21.5814 │     13.0592 │     31.1215 │
├─────────────────────┼─────────┼─────────────┼─────────────┤
│ 2013-01-01 01:00:00 │ 10.1830 │      3.9216 │     19.0128 │
├─────────────────────┼─────────┼─────────────┼─────────────┤
│ 2013-01-01 02:00:00 │  6.3195 │      2.4086 │     12.3438 │
├─────────────────────┼─────────┼─────────────┼─────────────┤
│ 2013-01-01 03:00:00 │  6.0749 │      1.4479 │     10.9812 │
├─────────────────────┼─────────┼─────────────┼─────────────┤
│ 2013-01-01 04:00:00 │  6.0749 │      1.9315 │     12.7713 │
├─────────────────────┼─────────┼─────────────┼─────────────┤
│ ...                 │     ... │         ... │         ... │
├─────────────────────┼─────────┼─────────────┼─────────────┤
│ 2013-01-02 07:00:00 │ 42.6970 │     23.3424 │     93.2515 │
├─────────────────────┼─────────┼─────────────┼─────────────┤
│ 2013-01-02 08:00:00 │ 70.6854 │     41.8467 │    156.6811 │
├─────────────────────┼─────────┼─────────────┼─────────────┤
│ 2013-01-02 09:00:00 │ 90.7043 │     44.4452 │    181.0452 │
├─────────────────────┼─────────┼─────────────┼─────────────┤
│ 2013-01-02 10:00:00 │ 88.7133 │     39.4447 │    169.7889 │
├─────────────────────┼─────────┼─────────────┼─────────────┤
│ 2013-01-02 11:00:00 │ 86.6475 │     32.0955 │    180.7717 │
└─────────────────────┴─────────┴─────────────┴─────────────┘
Code-only mode
Use forecast_code() when you want to preview or export the reproducible script without executing it. This is useful for code review, auditing the generated pipeline, or running the script in a separate environment.
# Generate the reproducible script without executing it
# ==============================================================================
code_result = assistant.forecast_code(
    data        = data,
    steps       = 36,
    test_size   = 36,
    profile     = profile,
    plan        = plan_refined
)
code_result.show_code()
The ForecastResult object
Both forecast() modes return a ForecastResult, a lightweight container that bundles everything the assistant used and produced.
| Attribute | Type | Description |
|---|---|---|
predictions |
DataFrame | Forecasted values. When intervals are requested, the bound columns are included alongside the point predictions. |
metrics |
DataFrame or None | Evaluation metrics (MAE, MSE, MASE, MAPE), one row per series. None in prediction mode. |
code |
str | The exact standalone skforecast script that produced the forecast, ready to run on its own. |
profile |
ForecastingProfile |
The data profile behind the forecast. |
plan |
ForecastPlan |
The detailed configuration that was executed. |
Backtesting
The backtesting branch uses the same profile and plan as the forecast branch but evaluates the model's historical performance through time series cross-validation. The key decision is how to configure the TimeSeriesFold object, which controls exactly how the historical data is partitioned into successive training and test windows.
skforecast-ai provides three distinct ways to define this validation strategy:
Explicit instantiation (recommended): manually construct a
TimeSeriesFoldand pass it directly tobacktest(). Use this when you already know your exact operational constraints.Deterministic
create_cv(): allow the assistant to derive a sensibleTimeSeriesFoldfrom the profile and plan using rule-based defaults. You can override individual parameters explicitly.LLM
create_cv()(with a prompt): describe your deployment use case in natural language. The LLM translates your description into a fully-configuredTimeSeriesFold, accompanied by an explanation you can audit.
Define the backtesting strategy
Manual TimeSeriesFold
# Create your own TimeSeriesFold object
# ==============================================================================
end_train = '2012-08-31 23:59:00'
cv = TimeSeriesFold(
    steps              = 36,
    initial_train_size = end_train,
    refit              = False,
    verbose            = False
)
cv
TimeSeriesFold
General Information
- Initial train size: 2012-08-31 23:59:00
- Initial train size as int: None
- Steps: 36
- Fold stride: 36
- Overlapping folds: False
- Window size: None
- Differentiation: None
- Refit: False
- Fixed train size: True
- Gap: 0
- Skip folds: None
- Allow incomplete fold: True
- Return all indexes: False
Deterministic create_cv()
Only initial_train_size is passed here; the rest of the strategy comes from the defaults. The explanation says which values you chose and why each default has its value.
# Let the assistant derive a TimeSeriesFold with rule-based defaults
# ==============================================================================
cv_det = assistant.create_cv(
    profile            = profile,
    plan               = plan_refined,
    initial_train_size = end_train,
)

cv_det
╭───────────────────────────── Cross-Validation Explanation ─────────────────────────────╮
│                                                                                        │
│  Initial training up to 2012-08-31 23:59:00, trained once (no refit), 36-step          │
│  horizon, 82 folds. Trained once by default: refitting in every fold would multiply    │
│  the training cost by the 82 folds. initial_train_size as requested.                   │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
        Cross-Validation Configuration
┏━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━┓
┃ Parameter             ┃               Value ┃
┡━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━┩
│ steps                 │                  36 │
├───────────────────────┼─────────────────────┤
│ initial_train_size    │ 2012-08-31 23:59:00 │
├───────────────────────┼─────────────────────┤
│ refit                 │               False │
├───────────────────────┼─────────────────────┤
│ fixed_train_size      │               False │
├───────────────────────┼─────────────────────┤
│ gap                   │                   0 │
├───────────────────────┼─────────────────────┤
│ fold_stride           │                  36 │
├───────────────────────┼─────────────────────┤
│ skip_folds            │                None │
├───────────────────────┼─────────────────────┤
│ allow_incomplete_fold │                True │
├───────────────────────┼─────────────────────┤
│ differentiation       │                None │
├───────────────────────┼─────────────────────┤
│ n_folds               │                  82 │
├───────────────────────┼─────────────────────┤
│ n_fits                │                   1 │
└───────────────────────┴─────────────────────┘
LLM create_cv() with a natural-language prompt
Rather than manually configuring TimeSeriesFold parameters, you can describe your backtesting strategy in natural language and let the assistant translate it into a rigorous cross-validation schema. The Agentic forecasting guide shows this translation in an animation.
# Let the assistant create the TimeSeriesFold from a natural-language prompt
# ==============================================================================
prompt = (
    "I forecast bike demand 36 hours ahead. "
    "The model should be trained once on all data up to the end of August 2012, 23:59. "
    "Do not refit the model as the window rolls forward."
)
cv_llm = assistant.create_cv(
    profile = profile,
    plan    = plan_refined,
    prompt  = prompt
)
# Cross-validation strategy derived from the prompt
# ==============================================================================
cv_llm
╭───────────────────────────── Cross-Validation Explanation ─────────────────────────────╮
│                                                                                        │
│  The model is trained once on all historical data up to the end of August 2012         │
│  ('2012-08-31 23:00:00') with refit=False as requested. This leaves 4 full months      │
│  (Sep–Dec 2012, ~2,928 hours) for backtesting evaluation across successive 36-hour     │
│  horizons, easily exceeding the 2-fold minimum requirement. Initial training up to     │
│  2012-08-31 23:00:00, trained once (no refit), 36-step horizon, 82 folds.              │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
        Cross-Validation Configuration
┏━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━┓
┃ Parameter             ┃               Value ┃
┡━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━┩
│ steps                 │                  36 │
├───────────────────────┼─────────────────────┤
│ initial_train_size    │ 2012-08-31 23:00:00 │
├───────────────────────┼─────────────────────┤
│ refit                 │               False │
├───────────────────────┼─────────────────────┤
│ fixed_train_size      │               False │
├───────────────────────┼─────────────────────┤
│ gap                   │                   0 │
├───────────────────────┼─────────────────────┤
│ fold_stride           │                  36 │
├───────────────────────┼─────────────────────┤
│ skip_folds            │                None │
├───────────────────────┼─────────────────────┤
│ allow_incomplete_fold │                True │
├───────────────────────┼─────────────────────┤
│ differentiation       │                None │
├───────────────────────┼─────────────────────┤
│ n_folds               │                  82 │
├───────────────────────┼─────────────────────┤
│ n_fits                │                   1 │
└───────────────────────┴─────────────────────┘
# LLM reasoning behind the TimeSeriesFold configuration
# ==============================================================================
print(textwrap.fill(cv_llm.explanation, width=88))
The model is trained once on all historical data up to the end of August 2012
('2012-08-31 23:00:00') with refit=False as requested. This leaves 4 full months
(Sep–Dec 2012, ~2,928 hours) for backtesting evaluation across successive 36-hour
horizons, easily exceeding the 2-fold minimum requirement. Initial training up to
2012-08-31 23:00:00, trained once (no refit), 36-step horizon, 82 folds.
Since the prompt correctly describes the intended use case, the cv_llm object returned by create_cv() is equivalent to the one we built manually (the same 82 folds; the timestamp is aligned to the hourly frequency). However, it was derived entirely from a natural-language description. The returned CVResult carries the splitter as cv_llm.cv and, as cv_llm.explanation, a description of the choices the assistant made, allowing you to verify that the resulting TimeSeriesFold matches your intended strategy before executing the backtest.
Run the backtest
# Run backtesting, reusing the pre-computed profile and plan
# ==============================================================================
results_backtest = assistant.backtest(
    data        = data,
    cv          = cv,           # TimeSeriesFold, or a CVResult from create_cv()
    interval    = [0.1, 0.9],   # 80% prediction interval
    profile     = profile,      # Reuse the pre-computed profile
    plan        = plan_refined  # Reuse the refined plan
)

results_backtest.show_explanation()
display(results_backtest.metrics)
display(results_backtest.predictions.head())
0%| | 0/82 [00:00<?, ?it/s]
╭───────────────────────────────── Backtest Explanation ─────────────────────────────────╮
│                                                                                        │
│  Initial training up to 2012-08-31 23:59:00, trained once (no refit), 36-step          │
│  horizon, 82 folds. Results: mean_absolute_error: 50.1874, mean_squared_error:         │
│  6935.7326, mean_absolute_scaled_error: 0.8185, mean_absolute_percentage_error:        │
│  0.5483.                                                                               │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
| mean_absolute_error | mean_squared_error | mean_absolute_scaled_error | mean_absolute_percentage_error | |
|---|---|---|---|---|
| 0 | 50.187384 | 6935.732623 | 0.818529 | 0.548273 |
| fold | pred | lower_bound | upper_bound | |
|---|---|---|---|---|
| 2012-09-01 00:00:00 | 0 | 122.935984 | 93.616739 | 153.673163 |
| 2012-09-01 01:00:00 | 0 | 115.683353 | 83.414275 | 146.211674 |
| 2012-09-01 02:00:00 | 0 | 73.660319 | 47.602204 | 104.086342 |
| 2012-09-01 03:00:00 | 0 | 45.817784 | 21.567420 | 69.256026 |
| 2012-09-01 04:00:00 | 0 | 19.884786 | 5.453657 | 37.048089 |
The plot opens on ten days of October, where the predictions, the actual values and the interval can be told apart. Double-click on it to see the whole test period, from September to December 2012.
# Plot prediction intervals vs real value
# ==============================================================================
predictions = results_backtest.predictions
data_test = data.set_index("date_time").loc[predictions.index, :]

fig = go.Figure([
    go.Scatter(name='Prediction', x=predictions.index, y=predictions['pred'], mode='lines'),
    go.Scatter(
        name='Real value', x=data_test.index, y=data_test['users'], mode='lines',
    ),
    go.Scatter(
        name='Upper Bound', x=predictions.index, y=predictions['upper_bound'], mode='lines',
        marker=dict(color="#444"), line=dict(width=0), showlegend=False
    ),
    go.Scatter(
        name='Lower Bound', x=predictions.index, y=predictions['lower_bound'], marker=dict(color="#444"),
        line=dict(width=0), mode='lines', fillcolor='rgba(68, 68, 68, 0.3)', fill='tonexty', showlegend=False
    )
])
fig.update_layout(
    title="Real value vs predicted in test data",
    xaxis_title="Date time",
    yaxis_title="users",
    width=800,
    height=400,
    margin=dict(l=20, r=20, t=35, b=20),
    hovermode="x",
    legend=dict(orientation="h", yanchor="top", y=1.1, xanchor="left", x=0.001),
    # Initial zoom on x axis betwee 1 oct to 10 oct
    xaxis=dict(range=['2012-10-01', '2012-10-10'])
)
fig.show()
# Ask the assistant to interpret the backtesting results
# ==============================================================================
answer = assistant.ask(
    prompt = (
        "Explain the results of this backtesting, including the strategy, metrics, "
        "and predictions. Is the model good enough to deploy?"
    ),
    context = results_backtest
)
answer.show_explanation()
/var/folders/wt/8tvn563d5v55nspfbydgqb9r0000gp/T/ipykernel_71015/2899763076.py:3: DataSentToLLMWarning: `send_data_to_llm=False` does not apply to `context`: the predicted values it carries are sent to the LLM, because a question about a result cannot be answered from summary statistics alone. Your input data is not sent: a result holds only the model's output, never the data it was fitted on. To keep predictions local, ask without `context`.
  answer = assistant.ask(
╭────────────────────────────────── Assistant Response ──────────────────────────────────╮
│                                                                                        │
│  The backtesting evaluated a ForecasterRecursive model with LGBMRegressor over 82      │
│  non-overlapping folds of 36 steps each, fitting once on data up to 2012-08-31         │
│  23:59:00 without refitting. Across 2928 evaluated points, the model achieved a mean   │
│  absolute error of 50.187384 and a mean absolute scaled error of 0.818529. Whether     │
│  the model is ready to deploy cannot be determined from the provided outputs alone,    │
│  as deployment acceptance criteria and operational tolerances are not available.       │
│                                                                                        │
│  Backtesting Strategy                                                                  │
│                                                                                        │
│   • Initial training window ended at 2012-08-31 23:59:00.                              │
│   • Forecast horizon: 36 steps per fold.                                               │
│   • Fold stride: 36 observations, resulting in contiguous, non-overlapping testing     │
│     periods.                                                                           │
│   • Refit strategy: refit=False with fixed_train_size=True, meaning the model was      │
│     fitted once (n_fits: 1) and tested across all 82 folds.                            │
│   • Gap: 0 observations between training and forecast windows.                         │
│                                                                                        │
│  Evaluation Metrics                                                                    │
│                                                                                        │
│   • mean_absolute_error: 50.187384                                                     │
│   • mean_squared_error: 6935.732623                                                    │
│   • mean_absolute_scaled_error: 0.818529                                               │
│   • mean_absolute_percentage_error: 0.548273                                           │
│   • Interpretation: The mean absolute scaled error is below 1, which means the model   │
│     beats the one-step naive forecast (last training value). Note that mean absolute   │
│     percentage error is a percentage and becomes unreliable as the target approaches   │
│     zero, which is pertinent because the target series has a minimum value of 1.       │
│                                                                                        │
│  Predictions Summary                                                                   │
│                                                                                        │
│   • Total predicted steps: 2928 observations across 82 folds.                          │
│   • Prediction interval: 80% coverage ([0.1, 0.9]) generated via bootstrapping.        │
│   • Point predictions (pred): minimum 0.9913779330166613, maximum 859.9199274681027,   │
│     mean 228.7613702369822.                                                            │
│   • Lower interval bound: minimum -2.743895653237591, maximum 798.2572409634424, mean  │
│     183.41207043556466.                                                                │
│   • Upper interval bound: minimum 6.341991034967448, maximum 893.6292721994874, mean   │
│     274.2824443850359.                                                                 │
│                                                                                        │
│  Deployment Readiness                                                                  │
│                                                                                        │
│   • It cannot be validated whether the model is ready for deployment because specific  │
│     business tolerances, error cost thresholds, and service-level targets are not      │
│     present in the context.                                                            │
│   • The model beats the one-step naive forecast (last training value) based on its     │
│     mean absolute scaled error of 0.818529, but whether an average deviation of        │
│     50.187384 users is acceptable depends on the application requirements.             │
│   • If you want to benchmark this pipeline against other models before deciding, you   │
│     can use assistant.compare() to evaluate candidate models on the same evaluation    │
│     setup.                                                                             │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
Code-only mode
Use backtest_code() to generate the reproducible backtesting script without executing it.
# Generate the reproducible backtest script without executing it
# ==============================================================================
code_bt = assistant.backtest_code(
    data        = data,
    cv          = cv,
    profile     = profile,
    plan        = plan_refined
)
code_bt.show_code()
The BacktestResult object
The backtest() method returns a BacktestResult, a lightweight container that bundles all the backtesting artifacts.
| Attribute | Type | Description |
|---|---|---|
predictions |
DataFrame | Full out-of-sample backtest predictions across all folds. |
metrics |
DataFrame | Backtesting metrics (MAE, MSE, MASE, MAPE), one row per series, computed across all folds. |
cv_config |
dict | Resolved TimeSeriesFold parameters for full traceability of the validation strategy. |
code |
str | The exact standalone skforecast script that reproduces the backtesting workflow. |
explanation |
str | Human-readable summary of the backtesting configuration and results. |
profile |
ForecastingProfile |
The data profile behind the backtest. |
plan |
ForecastPlan |
The detailed configuration that was executed. |
# Full results object
# ==============================================================================
results_backtest
╭───────────────────────────────── Backtest Explanation ─────────────────────────────────╮
│                                                                                        │
│  Initial training up to 2012-08-31 23:59:00, trained once (no refit), 36-step          │
│  horizon, 82 folds. Results: mean_absolute_error: 50.1874, mean_squared_error:         │
│  6935.7326, mean_absolute_scaled_error: 0.8185, mean_absolute_percentage_error:        │
│  0.5483.                                                                               │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
        Cross-Validation Configuration
┏━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━┓
┃ Parameter             ┃               Value ┃
┡━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━┩
│ steps                 │                  36 │
├───────────────────────┼─────────────────────┤
│ initial_train_size    │ 2012-08-31 23:59:00 │
├───────────────────────┼─────────────────────┤
│ refit                 │               False │
├───────────────────────┼─────────────────────┤
│ fixed_train_size      │                True │
├───────────────────────┼─────────────────────┤
│ gap                   │                   0 │
├───────────────────────┼─────────────────────┤
│ fold_stride           │                  36 │
├───────────────────────┼─────────────────────┤
│ skip_folds            │                None │
├───────────────────────┼─────────────────────┤
│ allow_incomplete_fold │                True │
├───────────────────────┼─────────────────────┤
│ differentiation       │                None │
├───────────────────────┼─────────────────────┤
│ n_folds               │                  82 │
├───────────────────────┼─────────────────────┤
│ n_fits                │                   1 │
└───────────────────────┴─────────────────────┘
                                     Backtest Metrics
┏━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━┓
┃ mean_absolute_error ┃ mean_squared_error ┃ mean_absolute_scale… ┃ mean_absolute_perce… ┃
┡━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━┩
│             50.1874 │          6935.7326 │               0.8185 │               0.5483 │
└─────────────────────┴────────────────────┴──────────────────────┴──────────────────────┘
                    Backtest Predictions (2928 rows)
┏━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━┳━━━━━━━━━━┳━━━━━━━━━━━━━┳━━━━━━━━━━━━━┓
┃ Index               ┃    fold ┃     pred ┃ lower_bound ┃ upper_bound ┃
┡━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━╇━━━━━━━━━━╇━━━━━━━━━━━━━╇━━━━━━━━━━━━━┩
│ 2012-09-01 00:00:00 │  0.0000 │ 122.9360 │     93.6167 │    153.6732 │
├─────────────────────┼─────────┼──────────┼─────────────┼─────────────┤
│ 2012-09-01 01:00:00 │  0.0000 │ 115.6834 │     83.4143 │    146.2117 │
├─────────────────────┼─────────┼──────────┼─────────────┼─────────────┤
│ 2012-09-01 02:00:00 │  0.0000 │  73.6603 │     47.6022 │    104.0863 │
├─────────────────────┼─────────┼──────────┼─────────────┼─────────────┤
│ 2012-09-01 03:00:00 │  0.0000 │  45.8178 │     21.5674 │     69.2560 │
├─────────────────────┼─────────┼──────────┼─────────────┼─────────────┤
│ 2012-09-01 04:00:00 │  0.0000 │  19.8848 │      5.4537 │     37.0481 │
├─────────────────────┼─────────┼──────────┼─────────────┼─────────────┤
│ ...                 │     ... │      ... │         ... │         ... │
├─────────────────────┼─────────┼──────────┼─────────────┼─────────────┤
│ 2012-12-31 19:00:00 │ 81.0000 │  80.6760 │     33.4467 │    109.1784 │
├─────────────────────┼─────────┼──────────┼─────────────┼─────────────┤
│ 2012-12-31 20:00:00 │ 81.0000 │  58.9545 │     19.4684 │     89.6922 │
├─────────────────────┼─────────┼──────────┼─────────────┼─────────────┤
│ 2012-12-31 21:00:00 │ 81.0000 │  36.4224 │     15.5316 │     62.6609 │
├─────────────────────┼─────────┼──────────┼─────────────┼─────────────┤
│ 2012-12-31 22:00:00 │ 81.0000 │  25.0615 │     11.4475 │     41.2955 │
├─────────────────────┼─────────┼──────────┼─────────────┼─────────────┤
│ 2012-12-31 23:00:00 │ 81.0000 │  16.0466 │      6.0405 │     30.4788 │
└─────────────────────┴─────────┴──────────┴─────────────┴─────────────┘
                          Dataset Profile
┏━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Property       ┃ Value                                          ┃
┡━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ Format         │ single                                         │
├────────────────┼────────────────────────────────────────────────┤
│ Series         │ 1                                              │
├────────────────┼────────────────────────────────────────────────┤
│ Observations   │ 17544                                          │
├────────────────┼────────────────────────────────────────────────┤
│ Frequency      │ h                                              │
├────────────────┼────────────────────────────────────────────────┤
│ Target         │ users                                          │
├────────────────┼────────────────────────────────────────────────┤
│ Exog columns   │ holiday, weather, temp  (categorical: weather) │
├────────────────┼────────────────────────────────────────────────┤
│ Missing values │ None                                           │
└────────────────┴────────────────────────────────────────────────┘

                                    Recommendation
┏━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Property              ┃ Value                                                       ┃
┡━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ Task type             │ single_series                                               │
├───────────────────────┼─────────────────────────────────────────────────────────────┤
│ Forecaster            │ ForecasterRecursive                                         │
├───────────────────────┼─────────────────────────────────────────────────────────────┤
│ Forecaster candidates │ ForecasterRecursive, ForecasterDirect, ForecasterFoundation │
├───────────────────────┼─────────────────────────────────────────────────────────────┤
│ Estimator             │ LGBMRegressor                                               │
├───────────────────────┼─────────────────────────────────────────────────────────────┤
│ Estimator candidates  │ LGBMRegressor, XGBRegressor, Ridge                          │
└───────────────────────┴─────────────────────────────────────────────────────────────┘

╭───────────────────────────────── Profile Explanation ──────────────────────────────────╮
│                                                                                        │
│  A single-series ML forecaster (ForecasterRecursive) is recommended. Data: 17544       │
│  observations, 'h' frequency. Alternative forecasters: ['ForecasterDirect',            │
│  'ForecasterFoundation']. Estimator: LGBMRegressor. A gradient boosting model is       │
│  preferred for a dataset of this size (17544 observations). Alternative estimators:    │
│  ['XGBRegressor', 'Ridge']. 3 exogenous variables (1 categorical) available as         │
│  predictors.                                                                           │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
                                      Forecast Plan
┏━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Property          ┃ Value                                                              ┃
┡━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ Task type         │ single_series                                                      │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Forecaster        │ ForecasterRecursive                                                │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Estimator         │ LGBMRegressor                                                      │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Steps             │ 36                                                                 │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Frequency         │ h                                                                  │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Lags              │ [1, 2, 3, 4, 23, 24, 25, 47, 48, 167, 168, 169]  (LLM-suggested)   │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Window features   │ [{'stats': ['mean', 'std'], 'window_size': 4}, {'stats': ['mean',  │
│                   │ 'max'], 'window_size': 24}, {'stats': ['mean'], 'window_size':     │
│                   │ 168}]  (LLM-suggested)                                             │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Calendar features │ ['hour', 'day_of_week', 'weekend', 'month'] (raw ordinal encoding) │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Use exog          │ True                                                               │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Interval          │ [0.1, 0.9]                                                         │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Interval method   │ bootstrapping                                                      │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Primary metric    │ mean_absolute_error                                                │
├───────────────────┼────────────────────────────────────────────────────────────────────┤
│ Preprocessing     │ 1 step                                                             │
└───────────────────┴────────────────────────────────────────────────────────────────────┘

                                   Preprocessing Steps
┏━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Step                    ┃ Reason                                                       ┃
┡━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ handle_categorical_exog │ Categorical exogenous variables detected: ['weather']. These │
│                         │ are handled automatically by skforecast                      │
│                         │ (categorical_features='auto').                               │
└─────────────────────────┴──────────────────────────────────────────────────────────────┘

╭─────────────────────────────────── Plan Explanation ───────────────────────────────────╮
│                                                                                        │
│  Plan: ForecasterRecursive + LGBMRegressor. Lags: [1, 2, 3, 4, 23, 24, 25, 47, 48,     │
│  167, 168, 169]. Window features: ['mean(window=4)', 'std(window=4)',                  │
│  'mean(window=24)', 'max(window=24)', 'mean(window=168)']. Calendar features:          │
│  ['hour', 'day_of_week', 'weekend', 'month'] (raw ordinal encoding). Prediction        │
│  intervals via bootstrapping. Exogenous variables included. MAE is interpretable,      │
│  robust to outliers, and works at any scale.                                           │
│                                                                                        │
│  LLM Refinement Reasoning: To capture the hourly bike rental dynamics described:       │
│                                                                                        │
│   • Lags 1 to 4 capture short-term autoregressive momentum and the recent hourly       │
│     trend.                                                                             │
│   • Lags 23, 24, 25, 47, and 48 capture daily periodicity (24 hours and 48 hours       │
│     prior) along with adjacent hourly shifts around daily rush hours.                  │
│   • Lags 167, 168, and 169 capture weekly seasonality (168 hours = 7 days), ensuring   │
│     the model aligns with the corresponding hour and day of the previous week          │
│     (differentiating weekday and weekend patterns).                                    │
│   • Rolling features across a 4-hour window (mean and standard deviation) capture      │
│     immediate trend and short-term demand variability.                                 │
│   • A 24-hour rolling window (mean and max) captures daily baseline demand and peak    │
│     rush-hour intensity.                                                               │
│   • A 168-hour rolling mean tracks weekly baseline level shifts.                       │
│                                                                                        │
│  Note: the LLM-suggested lags and window_features are hypotheses, not validated        │
│  improvements. Confirm any expected accuracy gain before relying on them.              │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
Comparing forecaster configurations
Choosing a forecasting model should not rely on intuition alone. Two configurations that look equally reasonable can perform very differently once evaluated on real temporal data. The most reliable approach is to test every candidate under identical conditions and compare their metrics.
The compare() method does exactly that. It receives a list of candidate configurations, backtests each one using the same TimeSeriesFold strategy, and returns a leaderboard ranked by the selected metric.
In the step-by-step path, the key argument is profile. Passing the profile computed at the beginning of this tutorial skips profiling entirely and guarantees that every candidate is evaluated against the same data profile. Note that compare() does not accept a plan: each candidate derives its own plan from the shared profile, which is precisely what makes the candidates differ.
Candidates can be provided in two ways:
Automatic candidates (
candidates=None): the assistant builds the comparison set from theprofile.forecaster_candidatesthat belong to the same family as the recommended forecaster, so every row is scored on the same thing. For multi-series data, a multi-series forecaster is never ranked against a multivariate one:ForecasterRecursiveMultiSeriesis compared withForecasterFoundation. This is useful when exploring a new dataset without a predefined shortlist. Whencvis theCVResultofcreate_cv()for a plan that is none of those candidates (a plan refined with another estimator or other lags, for example), that plan runs too, as the row'Strategy plan', and the summary names it.Explicit candidates (recommended): pass a list of
(name, config)tuples, wherenamelabels the row in the leaderboard andconfigholds the same override keys understood byplan():'forecaster','estimator','estimator_kwargs','lags','window_features','use_exog','differentiation','calendar_features','target_transformer'and'dropna_from_series'. This provides full control and makes the resulting table easier to interpret.
For a single series, compare() also adds a seasonal naive baseline (ForecasterEquivalentDate, which repeats the value of one seasonal period earlier, or the last value when the frequency has none) as one more row, ranked like the others, so the leaderboard shows whether a model beats the simplest reasonable forecast. Pass baseline=False to leave it out.
A failed candidate does not stop the comparison. Instead, a CandidateFailedWarning is issued, the row records the error and is placed last.
The Agentic forecasting guide shows a comparison in an animation: the candidates run through the same folds, and the leaderboard is a plain sort of the metric.
💡 Tip
All candidates use the same cross-validation strategy, ensuring a fair comparison. However, the results are only meaningful if the cv setup reflects the real use case where the model will be deployed. For example, if the production system retrains weekly, the backtest should also refit weekly. If the model is expected to forecast 24 hours ahead, the backtest should use a 24-hour horizon.
The evaluation window must also be representative. A period that is too short or dominated by unusual events (holidays, outages, or exceptional peaks) may favor a candidate that performs poorly over time. Define the validation setup carefully before comparing models so the final ranking is reliable.
Automatic candidates
# Compare the forecaster candidates suggested by the profile
# ==============================================================================
results_compare = assistant.compare(
    data        = data,
    cv          = cv,       # Same TimeSeriesFold used in the backtest above
    candidates  = None,     # Candidates suggested by the assistant
    profile     = profile   # Reuse the pre-computed profile
)
Comparing forecasters: 0%| | 0/4 [00:00<?, ?it/s]
Loading weights: 0%| | 0/92 [00:00<?, ?it/s]
# Ranked leaderboard
# ==============================================================================
results_compare.results
| rank | name | forecaster | estimator | mean_absolute_error | mean_squared_error | mean_absolute_scaled_error | mean_absolute_percentage_error | |
|---|---|---|---|---|---|---|---|---|
| 0 | 1 | ForecasterFoundation | ForecasterFoundation | autogluon/chronos-2-small | 38.436159 | 4231.325965 | 0.597467 | 0.611349 |
| 1 | 2 | ForecasterRecursive | ForecasterRecursive | LGBMRegressor | 46.312218 | 5495.881638 | 0.749598 | 0.472735 |
| 2 | 3 | ForecasterDirect | ForecasterDirect | LGBMRegressor | 49.298312 | 5936.622526 | 0.797930 | 0.499413 |
| 3 | 4 | Baseline (seasonal naive) | ForecasterEquivalentDate | None | 91.668716 | 22652.390710 | 1.503712 | 0.912133 |
# Deterministic summary of the comparison
# ==============================================================================
results_compare.show_explanation()
╭──────────────────────────────── Comparison Explanation ────────────────────────────────╮
│                                                                                        │
│  Compared 4 configurations, ranked ascending by mean_absolute_error. Shared            │
│  cross-validation strategy: Initial training up to 2012-08-31 23:59:00, trained once   │
│  (no refit), 36-step horizon, 82 folds. ForecasterFoundation is not trained: the       │
│  window and refit settings do not apply to it, each fold forecasts from the            │
│  observations before it. Best: 'ForecasterFoundation' (ForecasterFoundation /          │
│  autogluon/chronos-2-small) = 38.4362, 17.0% ahead of 'ForecasterRecursive'            │
│  (46.3122). All 3 configurations beat the baseline 'Baseline (seasonal naive)'         │
│  (91.6687). The best, 'ForecasterFoundation', beats it by 58.1%.                       │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
Explicit candidates
In practice, you will often already have a shortlist in mind: a fast baseline, a gradient boosting model, or a variant with a richer feature set. Passing explicit (name, config) tuples keeps the comparison focused and makes the resulting leaderboard easy to understand at a glance.
The config dictionary accepts the same overrides as plan(). Any omitted option falls back to the deterministic recommendation derived from the shared profile, so candidates can remain concise. For example, {'forecaster': 'ForecasterDirect'} changes only the forecaster while keeping the recommended estimator, lags, and features.
⚠️ Computational cost
Each candidate is backtested independently across all folds, so runtime increases with both the number and complexity of the configurations. Comparing four candidates will take roughly four times as long as running one backtest.
Start with a small set of clearly different options, review the results, and refine from there. Testing many near-identical variants is costly and rarely useful.
# Compare an explicit shortlist of configurations
# ==============================================================================
candidates = [
    (
        "ridge_baseline",
        {
            "forecaster": "ForecasterRecursive",
            "estimator" : "Ridge",
            "lags"      : 24,
        }
    ),
    (
        "lgbm_daily_lags",
        {
            "forecaster": "ForecasterRecursive",
            "estimator" : "LGBMRegressor",
            "lags"      : 24,
        }
    ),
    (
        "refined_plan",
        {
            "forecaster"      : plan_refined.forecaster,
            "estimator"       : plan_refined.estimator,
            "lags"            : plan_refined.forecaster_kwargs.get("lags"),
            "window_features" : plan_refined.forecaster_kwargs.get("window_features"),
        }
    ),
    (
        "lgbm_direct",
        {
            "forecaster": "ForecasterDirect",
            "estimator" : "LGBMRegressor",
            "lags"      : 24,
        }
    ),
    (
        "foundation_model",
        {
            "forecaster": "ForecasterFoundation"
        }
    ),
]

results_compare = assistant.compare(
    data        = data,
    cv          = cv,
    candidates  = candidates,  # Specific candidates to compare
    metric      = ['mean_absolute_error', 'mean_absolute_scaled_error'],
    profile     = profile
)
Comparing forecasters: 0%| | 0/6 [00:00<?, ?it/s]
Loading weights: 0%| | 0/92 [00:00<?, ?it/s]
The refined_plan candidate reuses the forecaster, estimator, lags and window features of the plan produced by refine_plan(). This is the recommended way to validate a refined plan: the leaderboard shows whether the extra domain knowledge actually improves the metrics compared to the deterministic baselines. Passing create_cv(profile=profile, plan=plan_refined) as cv with candidates=None does the same with the candidates of the profile: the refined plan is the row 'Strategy plan'.
When several metrics are requested, all of them are shown as columns but only the first one drives the ranking.
# Ranked leaderboard, sorted by the first metric requested
# ==============================================================================
results_compare.results
| rank | name | forecaster | estimator | mean_absolute_error | mean_absolute_scaled_error | |
|---|---|---|---|---|---|---|
| 0 | 1 | foundation_model | ForecasterFoundation | autogluon/chronos-2-small | 38.436159 | 0.597467 |
| 1 | 2 | refined_plan | ForecasterRecursive | LGBMRegressor | 50.187384 | 0.818529 |
| 2 | 3 | lgbm_direct | ForecasterDirect | LGBMRegressor | 50.224908 | 0.819189 |
| 3 | 4 | lgbm_daily_lags | ForecasterRecursive | LGBMRegressor | 55.517689 | 0.905517 |
| 4 | 5 | Baseline (seasonal naive) | ForecasterEquivalentDate | None | 91.668716 | 1.503712 |
| 5 | 6 | ridge_baseline | ForecasterRecursive | Ridge | 93.145620 | 1.519244 |
Inspect individual candidates
Because every candidate is a full BacktestResult, the details of any individual configuration remain available, including its metrics, its predictions and the standalone script that generated them.
# Inspect a specific candidate
# ==============================================================================
candidate = results_compare.candidates['foundation_model']

display(candidate.metrics)
display(candidate.predictions.head())
candidate.show_code()
| mean_absolute_error | mean_absolute_scaled_error | |
|---|---|---|
| 0 | 38.436159 | 0.597467 |
| level | fold | pred | |
|---|---|---|---|
| 2012-09-01 00:00:00 | users | 0 | 148.059464 |
| 2012-09-01 01:00:00 | users | 0 | 102.715004 |
| 2012-09-01 02:00:00 | users | 0 | 66.084412 |
| 2012-09-01 03:00:00 | users | 0 | 40.878693 |
| 2012-09-01 04:00:00 | users | 0 | 29.577866 |
Reuse the winning configuration
The most useful result of a comparison is often not the leaderboard, but best_candidate. It is a complete BacktestResult carrying both the winning profile and plan, so it can be fed back into the step-by-step workflow without manually rebuilding the configuration.
# Winning configuration
# ==============================================================================
print(f"Best candidate: {results_compare.best_name}")
results_compare.best_candidate.plan
Best candidate: foundation_model
                Forecast Plan
┏━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Property       ┃ Value                     ┃
┡━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ Task type      │ foundation                │
├────────────────┼───────────────────────────┤
│ Forecaster     │ ForecasterFoundation      │
├────────────────┼───────────────────────────┤
│ Estimator      │ autogluon/chronos-2-small │
├────────────────┼───────────────────────────┤
│ Steps          │ 36                        │
├────────────────┼───────────────────────────┤
│ Frequency      │ h                         │
├────────────────┼───────────────────────────┤
│ Use exog       │ True                      │
├────────────────┼───────────────────────────┤
│ Interval       │ None                      │
├────────────────┼───────────────────────────┤
│ Primary metric │ mean_absolute_error       │
├────────────────┼───────────────────────────┤
│ Preprocessing  │ 1 step                    │
└────────────────┴───────────────────────────┘

                                   Preprocessing Steps
┏━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Step                    ┃ Reason                                                       ┃
┡━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│ handle_categorical_exog │ Categorical exogenous variables detected: ['weather'].       │
│                         │ 'autogluon/chronos-2-small' consumes categorical covariates  │
│                         │ natively, so no encoding is needed.                          │
└─────────────────────────┴──────────────────────────────────────────────────────────────┘

╭─────────────────────────────────── Plan Explanation ───────────────────────────────────╮
│                                                                                        │
│  Plan: ForecasterFoundation + autogluon/chronos-2-small. No lag or window features:    │
│  the foundation model forecasts directly from the raw context window. Exogenous        │
│  variables included. Primary metric: mean_absolute_error, as requested; also           │
│  computed: mean_absolute_scaled_error. The model reads the last 8192 observations of   │
│  the series as context; the series has 17544, so older observations are not used.      │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
# Produce the final forecast with the winning configuration
# ==============================================================================
results_pred_best = assistant.forecast(
    data        = data,
    steps       = 36,
    interval    = [0.1, 0.9],
    test_size   = None,                                # Prediction mode
    exog        = exog,                                # Future values of exogenous variables
    profile     = results_compare.profile,             # Shared profile
    plan        = results_compare.best_candidate.plan  # Winning plan
)

results_pred_best.show_code()
Loading weights: 0%| | 0/92 [00:00<?, ?it/s]
Explain mode (comparison)
Like any other result, a ComparisonResult can be passed to ask() as context to have the ranking explained. The LLM restates what the leaderboard measured, not why one candidate beat another, and it cannot change the outcome: all metrics and rankings are computed deterministically before it sees the result.
# Ask the assistant to interpret the comparison
# ==============================================================================
answer = assistant.ask(
    prompt = (
        "Explain the comparison results. Is the margin between the top candidates "
        "meaningful, or are they practically equivalent?"
    ),
    context = results_compare
)
answer.show_explanation()
/var/folders/wt/8tvn563d5v55nspfbydgqb9r0000gp/T/ipykernel_71015/2209842622.py:3: DataSentToLLMWarning: `send_data_to_llm=False` does not apply to `context`: the predicted values it carries are sent to the LLM, because a question about a result cannot be answered from summary statistics alone. Your input data is not sent: a result holds only the model's output, never the data it was fitted on. To keep predictions local, ask without `context`.
  answer = assistant.ask(
╭────────────────────────────────── Assistant Response ──────────────────────────────────╮
│                                                                                        │
│  The comparison evaluated six candidates across 82 folds on a 36-step forecast         │
│  horizon, ranked in ascending order by mean_absolute_error. The top candidate is       │
│  foundation_model (ForecasterFoundation using autogluon/chronos-2-small) with a        │
│  mean_absolute_error of 38.436159, followed by refined_plan with 50.187384 and         │
│  lgbm_direct with 50.224908. Per-fold spread is not given, so whether the margin       │
│  between the top candidates is meaningful cannot be assessed.                          │
│                                                                                        │
│  Leaderboard Summary                                                                   │
│                                                                                        │
│  The evaluation produced the following rankings:                                       │
│                                                                                        │
│   • Rank 1: foundation_model (ForecasterFoundation, autogluon/chronos-2-small) with    │
│     mean_absolute_error of 38.436159 and mean_absolute_scaled_error of 0.597467.       │
│   • Rank 2: refined_plan (ForecasterRecursive, LGBMRegressor) with                     │
│     mean_absolute_error of 50.187384 and mean_absolute_scaled_error of 0.818529.       │
│   • Rank 3: lgbm_direct (ForecasterDirect, LGBMRegressor) with mean_absolute_error of  │
│     50.224908 and mean_absolute_scaled_error of 0.819189.                              │
│   • Rank 4: lgbm_daily_lags (ForecasterRecursive, LGBMRegressor) with                  │
│     mean_absolute_error of 55.517689 and mean_absolute_scaled_error of 0.905517.       │
│   • Rank 5: Baseline (seasonal naive) (ForecasterEquivalentDate) with                  │
│     mean_absolute_error of 91.668716 and mean_absolute_scaled_error of 1.503712.       │
│   • Rank 6: ridge_baseline (ForecasterRecursive, Ridge) with mean_absolute_error of    │
│     93.145620 and mean_absolute_scaled_error of 1.519244.                              │
│                                                                                        │
│  Assessing Margins Between Candidates                                                  │
│                                                                                        │
│   • The leaderboard reports the aggregate performance metrics across all 82 folds,     │
│     but per-fold metrics and fold-to-fold variance are not provided in the results.    │
│   • Because per-fold spread is not given, whether a margin is meaningful cannot be     │
│     assessed, and no gap calculation can establish equivalence or significance.        │
│   • The leaderboard reflects what metric values each configuration attained; it does   │
│     not provide underlying causes for why one candidate outperformed another.          │
│                                                                                        │
│  Benchmark Interpretation                                                              │
│                                                                                        │
│   • The top four models (foundation_model, refined_plan, lgbm_direct, and              │
│     lgbm_daily_lags) all recorded a mean_absolute_scaled_error below 1, meaning each   │
│     beat the one-step naive forecast (last training value).                            │
│   • Baseline (seasonal naive) and ridge_baseline each had a                            │
│     mean_absolute_scaled_error above 1, indicating that neither beat the one-step      │
│     naive forecast (last training value).                                              │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
The ComparisonResult object
The compare() method returns a ComparisonResult, which groups the shared setup, the ranked leaderboard, and the individual backtests in a single object.
| Attribute | Type | Description |
|---|---|---|
results |
DataFrame | Ranked leaderboard, one row per candidate, sorted best to worst. Columns: rank, name, forecaster, estimator, the metric columns, and error when at least one candidate failed. |
candidates |
dict | Mapping of candidate name to the full BacktestResult object. |
failures |
dict | Mapping of candidate name to a CandidateFailure describing why it failed. Empty when every candidate succeeds. |
ranking_metric |
str | Name of the metric used to sort results. |
cv_config |
dict | Resolved TimeSeriesFold parameters plus the resulting n_folds, applied identically to every candidate. |
profile |
ForecastingProfile |
The shared data profile behind every candidate. |
explanation |
str | Deterministic, human-readable summary of the comparison. |
best_name |
str | Name of the top-ranked candidate. |
best_candidate |
BacktestResult |
Top-ranked candidate as a complete BacktestResult. |
baseline_name |
str, None | Name of the seasonal naive baseline row, or None when no baseline was added (multi-series data, baseline=False, or a target with missing values or missing timestamps). |
# Full results object
# ==============================================================================
results_compare
╭──────────────────────────────── Comparison Explanation ────────────────────────────────╮
│                                                                                        │
│  Compared 6 configurations, ranked ascending by mean_absolute_error. Shared            │
│  cross-validation strategy: Initial training up to 2012-08-31 23:59:00, trained once   │
│  (no refit), 36-step horizon, 82 folds. ForecasterFoundation is not trained: the       │
│  window and refit settings do not apply to it, each fold forecasts from the            │
│  observations before it. Best: 'foundation_model' (ForecasterFoundation /              │
│  autogluon/chronos-2-small) = 38.4362, 23.4% ahead of 'refined_plan' (50.1874). 4 of   │
│  5 configurations beat the baseline 'Baseline (seasonal naive)' (91.6687);             │
│  'ridge_baseline' does not. The best, 'foundation_model', beats it by 58.1%.           │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
                                    Comparison Results
┏━━━━━━━┳━━━━━━┳━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━┳━━━━━━━━━━━━━┳━━━━━━━━━━━━━━┓
┃ Index ┃ rank ┃         name ┃   forecaster ┃    estimator ┃ mean_absol… ┃ mean_absolu… ┃
┡━━━━━━━╇━━━━━━╇━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━╇━━━━━━━━━━━━━╇━━━━━━━━━━━━━━┩
│ 0     │    1 │ foundation_… │ ForecasterF… │ autogluon/c… │     38.4362 │       0.5975 │
├───────┼──────┼──────────────┼──────────────┼──────────────┼─────────────┼──────────────┤
│ 1     │    2 │ refined_plan │ ForecasterR… │ LGBMRegress… │     50.1874 │       0.8185 │
├───────┼──────┼──────────────┼──────────────┼──────────────┼─────────────┼──────────────┤
│ 2     │    3 │  lgbm_direct │ ForecasterD… │ LGBMRegress… │     50.2249 │       0.8192 │
├───────┼──────┼──────────────┼──────────────┼──────────────┼─────────────┼──────────────┤
│ 3     │    4 │ lgbm_daily_… │ ForecasterR… │ LGBMRegress… │     55.5177 │       0.9055 │
├───────┼──────┼──────────────┼──────────────┼──────────────┼─────────────┼──────────────┤
│ 4     │    5 │     Baseline │ ForecasterE… │          N/A │     91.6687 │       1.5037 │
│       │      │    (seasonal │              │              │             │              │
│       │      │       naive) │              │              │             │              │
├───────┼──────┼──────────────┼──────────────┼──────────────┼─────────────┼──────────────┤
│ 5     │    6 │ ridge_basel… │ ForecasterR… │        Ridge │     93.1456 │       1.5192 │
└───────┴──────┴──────────────┴──────────────┴──────────────┴─────────────┴──────────────┘
Reproducible code
Every forecast or backtest workflow exposes the standalone skforecast script used to produce its results. This script is strictly deterministic, ensuring identical outputs for a given set of inputs and configurations. You can access the code at any time via the show_code() method.
Free-form Q&A
The ask() method is not limited to interpreting workflow objects. Without any context attached, it works as a general forecasting knowledge assistant, useful for clarifying methodology, choosing between approaches, or understanding metric trade-offs.
Without a context there is no task type to route on, so only the general choosing-a-forecaster skill is sent unless the question mentions a topic (intervals, backtesting, metrics, ...) that pulls in a specific one. Pass skills= to pick them yourself; the names sent are recorded in answer.skills. See Skills for the LLM.
# Ask a general forecasting question (no data or result required)
# ==============================================================================
answer = assistant.ask(
    prompt = (
        "For hourly demand with strong daily and weekly seasonality, when should "
        "I prefer a direct forecasting strategy over a recursive one?"
    )
)
answer.show_explanation()
╭────────────────────────────────── Assistant Response ──────────────────────────────────╮
│                                                                                        │
│  You should prefer a direct forecasting strategy (ForecasterDirect) when the           │
│  predictive relationship between inputs and hourly demand changes substantially        │
│  across the forecast horizon, such as when the next few hours rely on recent momentum  │
│  while later hours depend primarily on time-of-day or day-of-week patterns. It is      │
│  also advantageous when recursive forecasting suffers from noticeable error            │
│  propagation over longer multi-step horizons, provided your forecast horizon is fixed  │
│  in advance. For most standard setups, however, ForecasterRecursive remains the        │
│  primary starting recommendation because it trains only a single model.                │
│                                                                                        │
│  When to Choose Direct Forecasting                                                     │
│                                                                                        │
│   • Step-specific relationships: In hourly demand with dual seasonality, predicting 1  │
│     hour ahead relies heavily on immediate autocorrelation, whereas predicting 24 or   │
│     168 hours ahead depends on structural seasonal patterns. ForecasterDirect trains   │
│     an independent estimator for each step, allowing each model to learn               │
│     step-specific dynamics.                                                            │
│   • Mitigating error propagation: ForecasterRecursive uses predicted values from       │
│     earlier steps as lag inputs for subsequent steps, which can compound errors        │
│     across long horizons. Direct models condition directly on observed historical      │
│     data, eliminating this feedback loop.                                              │
│   • Predefined forecast horizons: If your production system always generates           │
│     forecasts for a fixed horizon (such as a standard 24-hour day-ahead demand         │
│     forecast), the fixed steps requirement of ForecasterDirect is not a limitation.    │
│                                                                                        │
│  Trade-offs to Keep in Mind                                                            │
│                                                                                        │
│   • Computational cost: Direct forecasting trains N separate models for an N-step      │
│     horizon (for example, 24 models for 24 hours). This requires more memory and       │
│     training time, though training can be parallelized using the n_jobs parameter.     │
│   • Inflexible horizon: ForecasterDirect requires setting steps at initialization and  │
│     cannot forecast beyond that specified horizon at prediction time, unlike           │
│     ForecasterRecursive which can forecast any number of steps on demand.              │
│                                                                                        │
╰────────────────────────────────────────────────────────────────────────────────────────╯
Summary
This tutorial covered the step-by-step path of skforecast-ai. Here is a recap of what each stage does and when to use it:
| Step | Method | When to use |
|---|---|---|
| 1. Profile | profile() |
Always: produces the ForecastingProfile required by all downstream methods. |
| 2. Plan | plan() |
Always: converts the profile into an executable configuration. |
| 3. Refine plan | refine_plan() |
Optional: use when you want to override specific decisions (deterministic) or inject domain knowledge (LLM). Always evaluate the result. |
| 4a. Forecast | forecast() |
When you want future predictions or a held-out evaluation in a single execution. |
| 4a. Code only | forecast_code() |
When you want to preview or export the script without running it. |
| 4b. CV strategy | create_cv() |
When you want the assistant to derive or translate a TimeSeriesFold for you. |
| 4b. Backtest | backtest() |
When you want to evaluate the model over multiple historical folds. |
| 4b. Code only | backtest_code() |
When you want to preview or export the backtesting script without running it. |
| 4c. Compare | compare() |
When you want to rank several configurations under an identical cross-validation strategy and reuse the winner. |
| Any time | ask() |
When you want an LLM explanation of any intermediate object or result, or a general forecasting Q&A. |
The key advantage of this path is that the profile and plan are built once and reused across both the forecast and backtest branches. This avoids redundant profiling and ensures that both branches use the same modeling configuration. The same profile can also be handed to compare(), so every candidate is ranked against the very same data profile.
For a faster alternative that runs the entire pipeline in a single call, see the fast-path tutorial. For a comprehensive overview of backtesting mechanics, see the skforecast backtesting user guide.